

Requirements
Multi-turn GRPO needs a model with generator support and a model resource withnum_generator_replicas of one or more.
How an episode runs
Each episode starts from a task, which carries the prompt, the target the reward checks against, and any metadata the environment needs. The loop then alternates between the model and the environment:- The environment returns the task’s opening messages, typically a system prompt and the user prompt.
- The loop renders the messages and the environment’s tool specs into a prompt with the model’s chat template, samples a reply from the model, then parses it into an assistant message with any tool calls.
- The environment executes any tool calls in the assistant message and appends the results to the conversation history. It returns the updated history, a reward, and whether the episode is over.
- Steps 2 and 3 repeat until the environment marks the episode complete or the episode is truncated.
Env, and the cookbook runs the loop. When you write your own loop, your code both runs the loop and acts as the environment.
How episodes become training samples
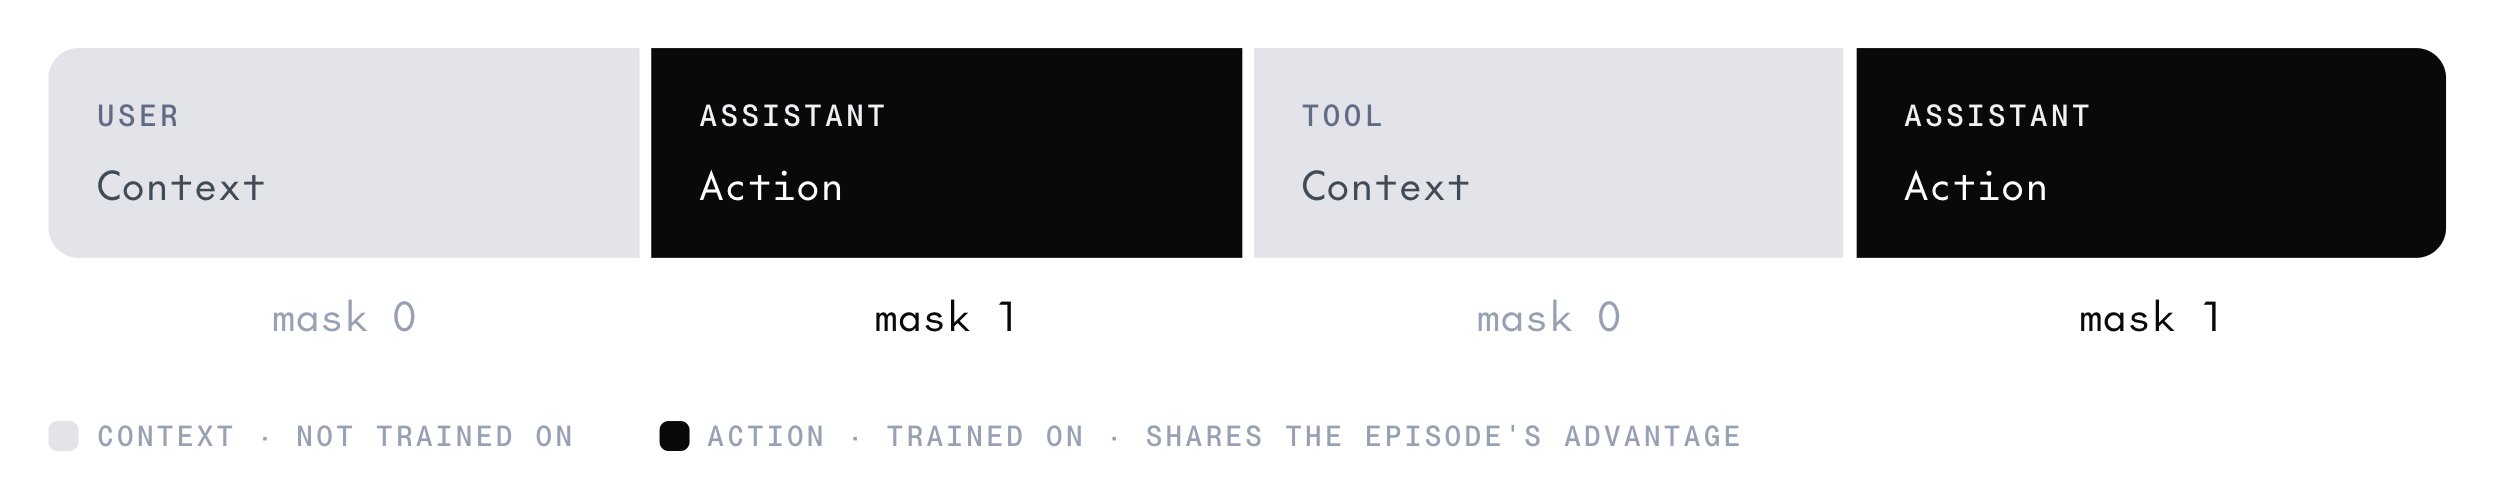
0, so the model isn’t trained to predict them. Action segments get loss mask 1, and every action in the episode carries the episode’s advantage.
Each action segment holds the tokens the generator sampled and the log-probabilities it returned for them, not a re-rendering of the parsed reply. The trainer’s importance ratio compares its own log-probabilities with the generator’s token by token, so both must cover the same tokens.
When the chat template strips earlier content from history, such as a reasoning model’s <think> blocks, the loop starts a new training sequence at that point, so the tokens stay aligned with the log-probabilities the generator recorded.
Truncation
An episode is truncated when it ends without the environment marking it complete. That happens when the conversation fills the context budget, the episode hits its turn limit, the environment cuts the episode short, or a sampled message can’t be parsed. Handle truncated episodes covers how the cookbook penalizes and masks truncated episodes.Next steps
Multi-turn recipes
Write an environment and train on it with the cookbook.
Reinforcement learning with GRPO
Learn how a GRPO step runs and how rewards become advantages.
Monitor training runs
Track how many turns episodes take and how they end.